Lighter intelligence, harder work
The problem we want to solve at UpServe is clear. Make it possible for a lighter intelligence to handle harder work. In doing so, reduce the time and money our customers spend, and grow together with them.
By a lighter intelligence, we mean an AI that uses fewer resources to do the work. Understanding long documents, comparing many conditions, and making calls in ambiguous situations all take a high level of intelligence. At the same time, once you hand that work over every day, cost starts to matter. What it costs to get one good result feels very different from what it costs to run the same work for months.
So we have been thinking about how to spend intelligence. Could we use ample intelligence to understand the work and design the method, and then use a lighter intelligence to carry out the everyday work by following that method?
It helps to picture how people work. A new task takes a lot of thought. You have to find where the information lives, decide what order to work in, and learn where mistakes tend to happen. With experience come guidelines and tools. The next time you do the same work, you can start from there.
We want to give AI that kind of working environment too.
Say a fictional distribution company hands over its quoting work. A request lists hundreds of items, and the names customers write differ a little from the product names in the catalog. The unit on the price list may not match the unit on the order. Someone has to find each product, check the conditions, calculate the price, and fill in the customer’s form without missing anything.
This work mixes parts that need judgment with parts that must be done exactly. Choosing the right product among similar ones takes judgment. Unit conversion and arithmetic can be handled by tools. Remembering which rows are still open and checking for gaps is something an execution structure can help with.
If we find the needed information for the AI, present what it has to decide in the right form, and hand calculation and checking to tools, we can lighten the load the AI has to carry. A lighter intelligence can then put its ability where it matters: on the judgments that actually need it.
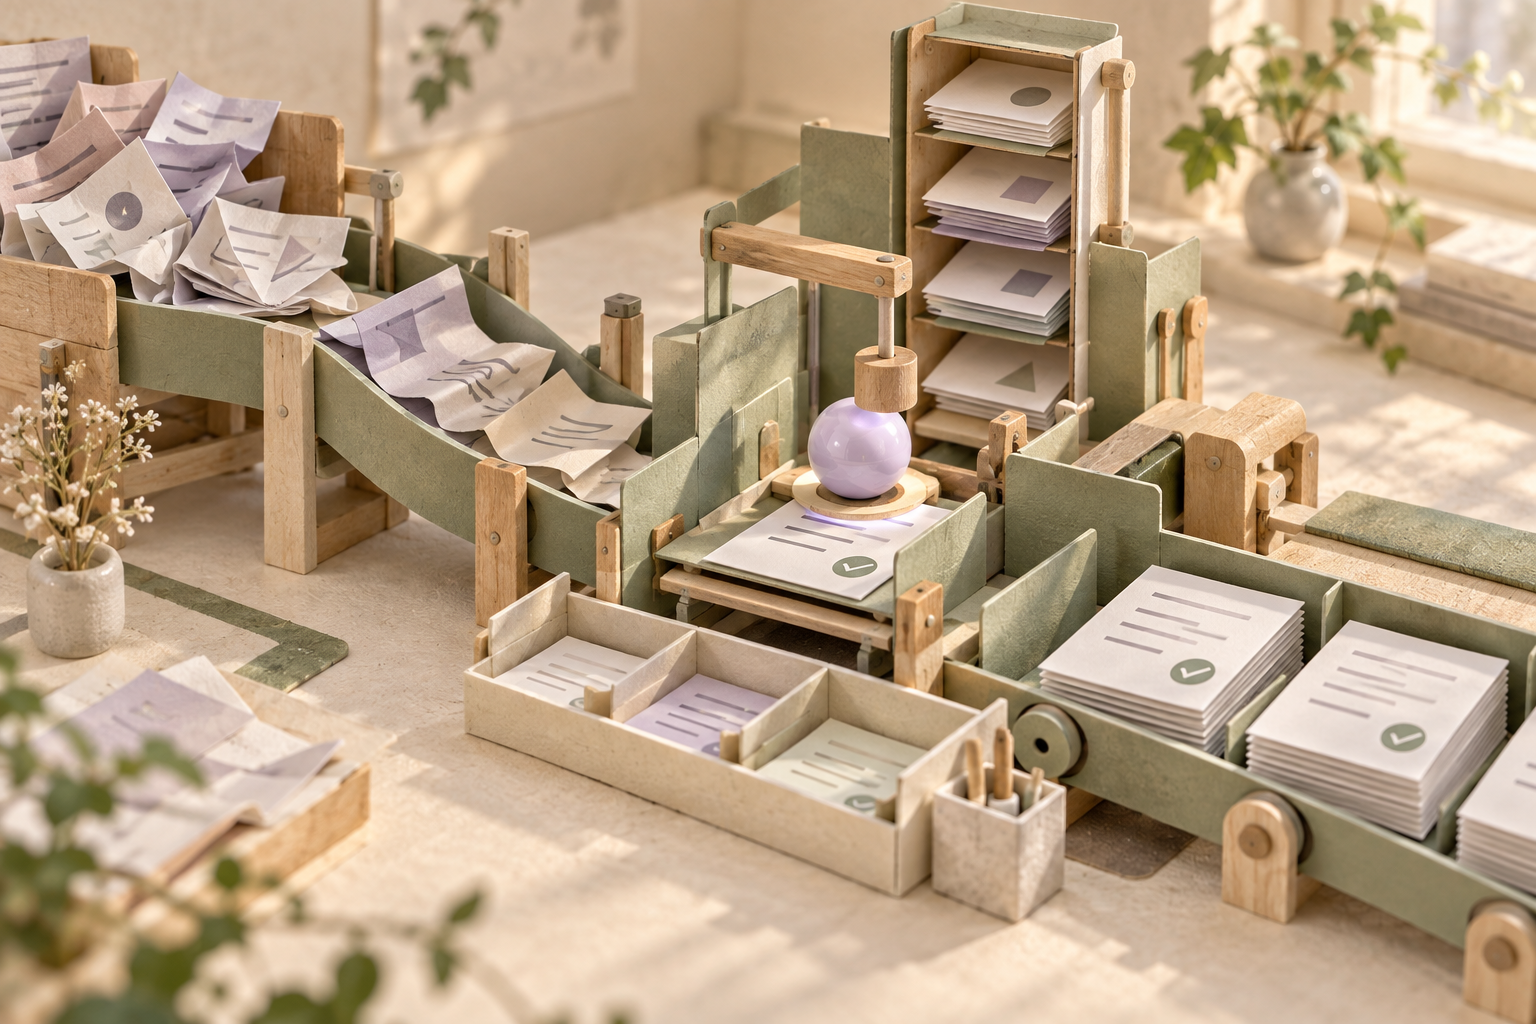
We call this execution environment a “harness.” It includes the tools the AI uses, the knowledge of the work, the order in which the work proceeds, and the ways to check results and recover from errors. An on-demand harness means preparing such an environment to fit the work being handed over.
Someone handling quotes needs an environment for comparing products and checking prices. Someone reviewing documents needs one for finding evidence and spotting missing conditions. By assembling the abilities and procedures each job needs, we aim to raise the level of work the same intelligence can handle.
Building that environment is where we can afford a higher level of intelligence: analyzing the work, choosing the tools it needs, designing the execution procedure, and fixing the problems that testing reveals. If a well-built structure can be used again and again, the effort that went into preparing it creates value across many runs that follow.
If people had to do all of this preparation for every customer, time and cost would grow again. So we are experimenting with whether AI can take on generating, verifying, and revising the harness as well. The direction is for customers to describe their work and the results they want, and for the service to prepare the environment to carry it out.
Of course, this is a hypothesis that results have to confirm. Right now, on quoting work, we are comparing how well the work gets done under different execution structures while keeping the model and the data the same. We want to confirm the effect of the structure first, and then, on that footing, test how far a lighter intelligence can go.
The effect of an expert harness built by people and the ability of AI to build that harness on its own have to be checked separately. We also need to see whether results from one kind of work can be reproduced in others, and whether repeated operation pays off once the cost of preparation and testing is included. We are not yet at a point where we can say this approach applies to every kind of work.
The cost we have to look at here also includes the customer’s time.
Even a cheaply made quote is a burden if a person has to recheck it from start to finish. We have to count the time spent finding gaps, fixing wrong values, and restarting stalled work. The goal is to lower the total cost of getting one piece of work properly done.
That is why we look at accuracy, completion rate, how often a person had to step in, processing time, and run cost together. Customers benefit only when they can trust the results while a lighter intelligence does the work.
We are also clear about which decisions belong to the customer. What counts as a good result, how far the service may act, and how much it may spend are for the customer to decide. The service should work within those limits and bring back the exceptions that truly need the customer’s judgment. Errors in internal tools and recurring processing problems are ours to reduce.
The longer work is entrusted to us, the more should accumulate in that relationship. The exceptions customers point out, the results they correct, and the new standards they set should help with the next piece of work. Places where the work keeps getting stuck become reasons to improve the execution structure, and accepted results can become test cases that check whether quality holds after each improvement.
When that kind of accumulation happens, customers can spend less time repeating the same explanations and corrections. We, in turn, can build better execution environments through real work. As the customer’s business evolves, the work the AI employee has to do changes too, and we picture a relationship where we learn together as it changes.
With the time saved, customers can meet their next client, prepare a new product, or make the decisions they had been putting off. And if operating costs fall, there is room to use AI for work that used to cost too much to hand over.
Getting harder work done with a lighter intelligence. And giving customers room in time and money as a result. We hope that room leads to our customers’ next stage of growth, and that UpServe grows alongside them.