We Run Our Business in a Loop
When you're developing with Claude Code or Codex, there are moments when the agent stops coding and asks a question. Even though you've already agreed on what to build.
Should this information go in an existing table or a new one? Should we solve this within the feature, or build something shared that other parts of the service can use? Do we handle only what we need today, or make room for cases that might come later?
Here's a hypothetical example of that kind of choice.
Say the plan is to track the processing status of each customer. The agent starts by adding a status column. Then it decides we probably need a reason for each change, a timestamp, the previous status, and a few more settings to handle future exceptions.
Each addition has a reason. But the service might already have a way to record change history. Another feature might already manage the same status. Miss that context, and you end up storing the same information in two places, or adding columns and settings nobody uses yet.
This is where a person steps in: “We already handle that over here.” “For now, we only need to support this case.” They aren't writing the code for the agent, but their choice can make a big difference to what gets built.
What if we replace the person answering those questions with another AI? One AI asks, another chooses, and the first goes back to implementing and checking. The loop can keep moving without waiting for a person. But if the AI making the choices is also missing the wider context, a series of reasonable-sounding decisions can take the result somewhere nobody intended.
This is one way the overengineering we watch out for with coding agents happens. The plan hasn't changed, yet implementing it produces a much bigger structure than we need. Passing the tests doesn't mean the design is the best fit for our service.
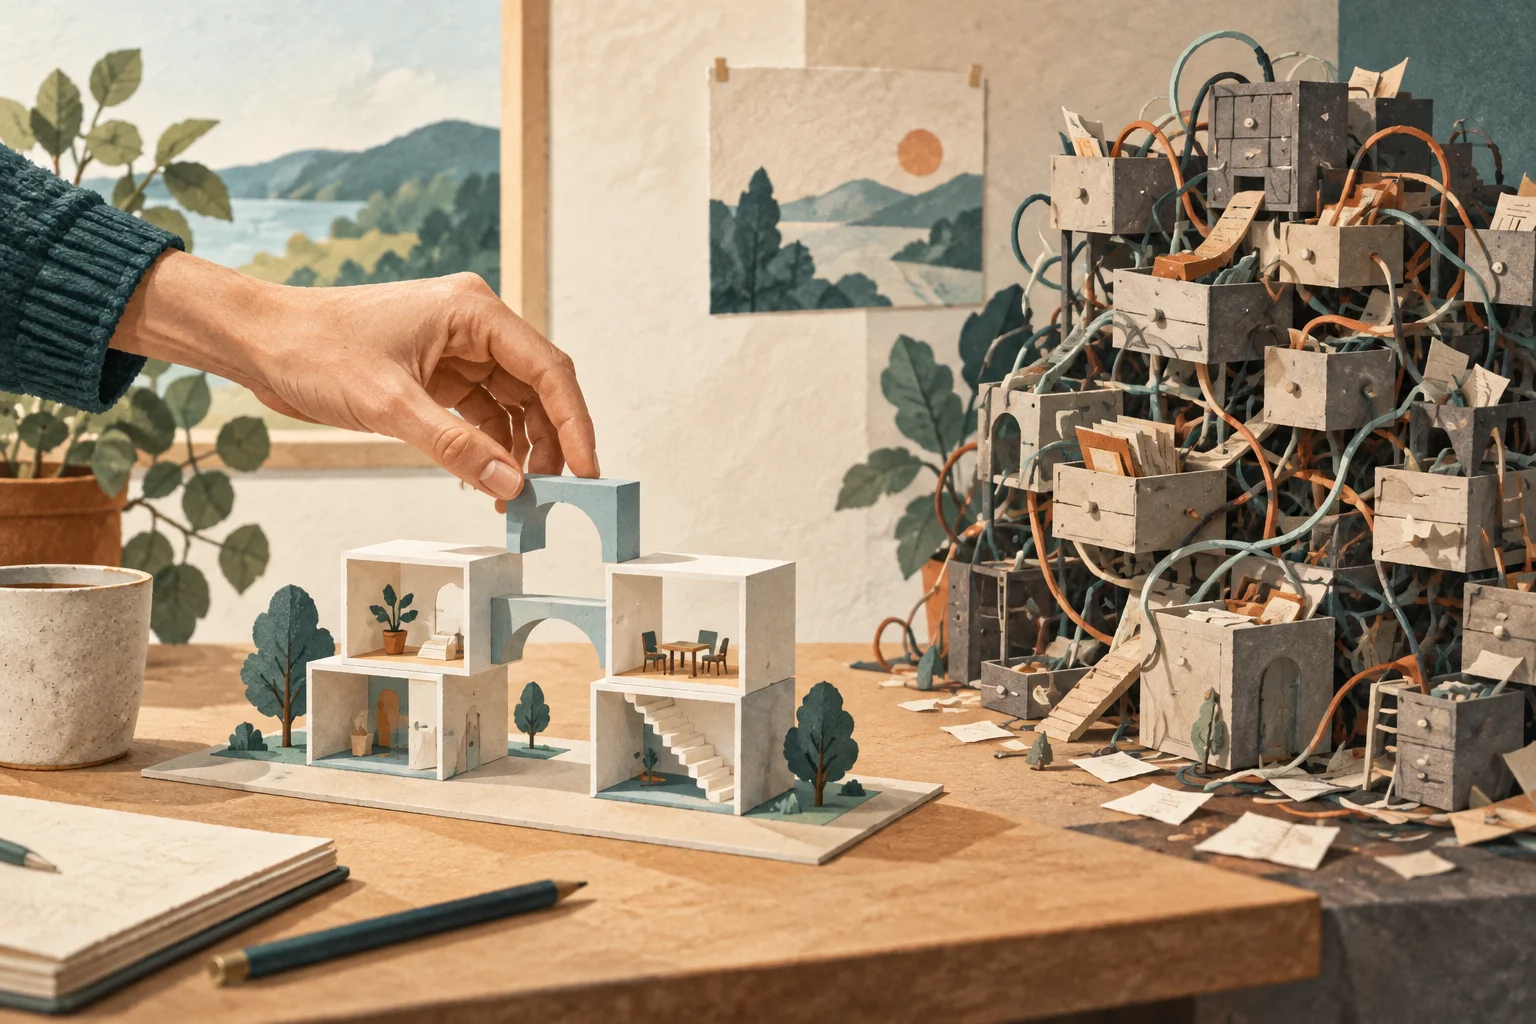
Important design choices need the context of the whole service.
That's why I'm cautious about closing the loop completely in software development. A good feature spec doesn't make every important choice disappear. There are still decisions that benefit from someone who knows how the service works today and how much of it we actually want to change.
And yet, at UpServe, we run our business in a loop. We say to be careful about it in coding, then want to keep it going in business.
I find that difference interesting.
In business, we often know the goal without knowing how to get there. Say we want to book ten conversations this month with companies that could actually use our service. This is a hypothetical goal, just to make the idea concrete.
We could write about a relevant problem, reach out to potential customers, or get introductions through partners. We have to try things to find out what works. Even if we choose writing, the path branches again depending on the industry we write for and the problem we address.
Here, faithfully completing the original plan isn't enough. We could finish ten articles and book no conversations at all. At that point, we need more than a report saying “plan complete.” We need to look at the result and choose what to try next.
I think of this as a search.
In computer science terms, BFS and DFS come to mind. Breadth-first search looks across several branches; depth-first search follows one branch further down. I don't mean we literally run a business with either algorithm. They're useful ways to think about where to spend the next attempt.
We might start with small experiments in content, direct outreach, and partner introductions. We're looking broadly for a response. If companies in a particular industry start asking about our service after reading our content, we can go deeper into that industry's problems. Look at which articles prompted inquiries, make more useful material around related problems, and improve the path from reading to a conversation.
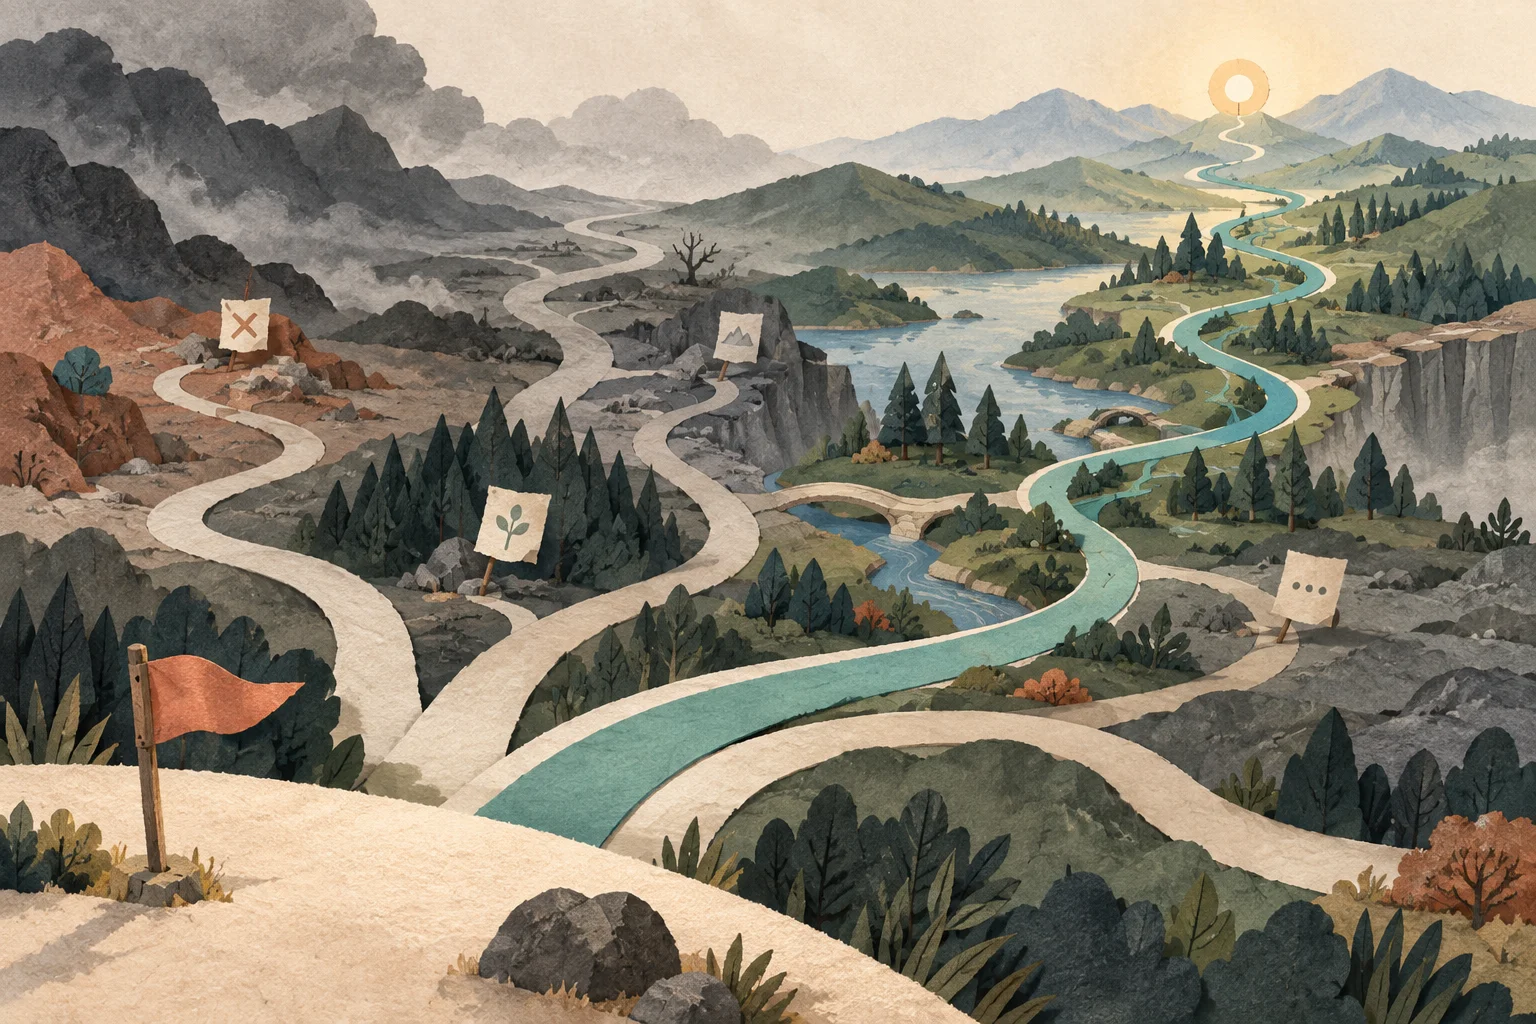
Look broadly at first, then go deeper where there's promise.
If we've given one path a fair try and there's no response, we can return to another branch. A response doesn't immediately make a path the right answer, either. We need to see whether it was a fluke or whether it happens again. And we don't have the time or money to test every approach equally, so cost and the wait for results matter alongside potential.
An agent loop fits this kind of work. Look at the goal, choose the next attempt, do the work, check what happened, and use that to make the next choice.
The result can't just be the agent writing, “That seems to have gone well.” Publishing an article or sending a message is a record of an action. Booking a conversation is a business result. Doing more of the former doesn't, by itself, mean we're closer to the latter.
We also shouldn't count an unanswered message as a failure straight away. Some things take time, and sometimes the measurement itself isn't working. Refreshing the same screen over and over doesn't create new evidence.
So a loop needs to remember a few things: what we tried, why we chose it, what happened, and what we'll change next. Without that record, an agent can present last week's failed idea as today's new one. It stays busy while going in circles.
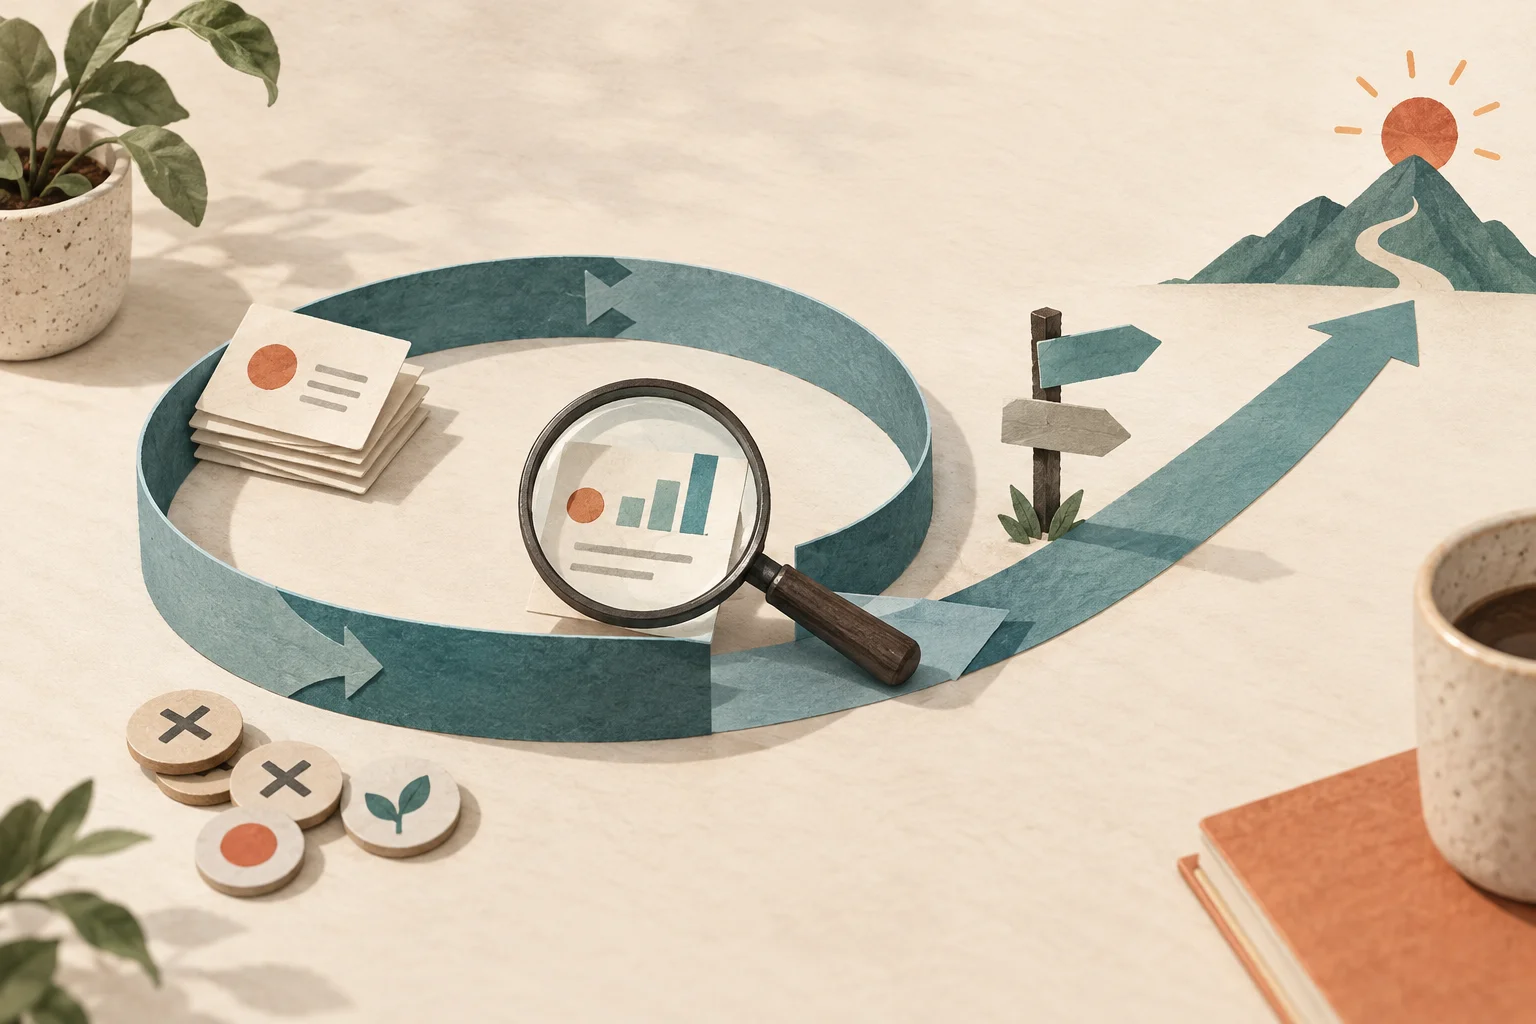
What we tried and what happened should change the next choice.
We put this distinction at the center of how we designed the team goal loop in UpServe. The team lead chooses a path toward the goal, assigns the work, and uses the results to judge the next approach. If the goal itself needs to change, that decision comes back to a person.
If “ten conversations” isn't happening, the agent can't quietly change the goal to “ten thousand page views.” That would be changing the scorecard, not reaching the goal. Which accounts it uses, whom it contacts, and how much it can spend also need to stay within the scope we gave it. If it needs new authority, we have to agree on that part again.
Of course, development involves search too, and business includes work with a clearly defined finish. Finding the cause of a bug means testing hypotheses. Issuing an invoice with agreed details has a clear completion criterion, even though it's a business task.
Business agents don't get a free pass to ignore context. But when a strategy can be tested on a small scale within an agreed goal and scope, its results can inform the next choice. Trying a different article topic or customer segment has different consequences, and a different route to correction, from choosing a data structure that affects the whole service. How much we put in the loop should depend on the impact of the choice and whether we can observe its result.
Choosing a KPI is a start. But if we book meetings with companies that aren't a good fit just to increase the count, all we've improved is the number. We need to agree on what counts, how long we'll give it, and which methods we won't use. If we've tried enough without useful evidence, or progress would require going beyond the agreed scope, the decision should come back to a person instead of the loop just continuing. Once we reach the goal, we can confirm the result and decide on the next one.
It's the work in between that we want to put in the loop. The goal hasn't changed, but the first approach didn't work, so the agent reads the results and tries a second one. If that starts working, it goes a little deeper.
If a person has to say “Okay, try this next” every time for the business to keep moving, the person is still running the loop.
We want to entrust AI with choosing that next attempt, too. That's why we run our business in a loop.